

Maximum of 25 job preferences reached.
Top Remote Senior Site Reliability Engineer Jobs in Austin, TX
Software
Operate and maintain highly available, secure, containerized SaaS applications across AWS and Azure. Responsibilities include rotating 24x7 on-call coverage, observability, incident and security response, disaster recovery, Terraform infrastructure-as-code, CI/CD automation, cloud integration, performance optimization, and developing AI agents to automate SRE and DevSecOps workflows.
Top Skills:
Amazon Web ServicesCheckovClaude CodeDatadogDockerDynatraceGithub ActionsGitlab CiGoJavaScriptKubernetesAzureNew RelicPrisma CloudPythonTerraformWiz

Cybersecurity
Owns the FedRAMP-authorized AWS GovCloud environment, ensuring reliability, security, compliance, patching, vulnerability remediation, continuous monitoring, deployments, hardening, audits, incident response, and on-call support. The role requires hands-on Kubernetes, AWS, infrastructure-as-code, CI/CD, vulnerability management, automation, and regulated-environment experience, while collaborating with SRE and security teams.
Top Skills:
AnsibleAws GovcloudCloudFormationFips-Validated CryptographyGithub ActionsGoJenkinsKubernetesNessusOpenscapPythonQualysRubySIEMTenableTerraform

Big Data • Cloud • Software • Database
Seeking a Site Reliability Engineer with expertise in networking and distributed systems for building secure multi-cloud infrastructure. Responsibilities include maintaining network architecture and ensuring reliable service-to-service communication, involving a 24/7 on-call rotation.
Top Skills:
AWSAzureBgpDnsGCPIpv6KubernetesLoad BalancingMtlsService MeshTcp/IpTlsVpcsVpns
Reposted One Month AgoSaved
Software • Defense
Work as an SRE embedded with product teams to improve reliability by fixing application code (primarily TypeScript), building observability (Prometheus, Loki, Grafana, Alloy), defining SLIs/SLOs, leading incident response and postmortems, automating toil, and supporting deployments across on‑prem DoD and AWS environments.
Top Skills:
AlloyAWSBashContainersDockerGithub ActionsGitlab Ci/CdGoGrafanaJenkinsKubectlKubernetesLokiNode.jsPrometheusPythonTypescript
Information Technology • Security • Software • Cybersecurity
Owns production reliability for high-throughput, low-latency systems, including observability, SLOs, incident response, capacity planning, infrastructure as code, progressive delivery, chaos testing, and operational tooling. The role requires hands-on software and infrastructure engineering, production Redis/ElastiCache expertise, cloud infrastructure knowledge, security awareness, mentoring, and participation in on-call operations.
Top Skills:
AWSDatadogEksElasticacheGoGrafanaKubernetesOpentelemetryPrometheusPythonRedisTerraform
Big Data • Software
Owns production reliability for a B2B SaaS platform, including SLOs, error budgets, observability, alerting, incident response, recovery exercises, performance and capacity engineering, load testing, disaster recovery, and production readiness. The role writes automation and production code, leads incidents, coaches engineering teams, and improves reliability across Kubernetes, Azure, databases, messaging, and service infrastructure.
Top Skills:
.NetAksAsp.NetAWSAzureAzure Service BusC#Dora MetricsFluxGatlingGitopsGoGrafanaIncident.IoIstioJmeterK6KafkaKubernetesLokiMongoDBNist 800-171PagerdutyPrometheusPythonSentrySignalrSoc 2TempoTemporalTypescript

Software
Own reliability, performance, scalability, and operational standards across on-premises, private-cloud, and AWS environments. Build infrastructure-as-code, deployment automation, monitoring, alerting, and observability tooling; define SLOs, SLIs, error budgets, and readiness standards. Lead incident response, root-cause analysis, disaster-recovery readiness, release coordination, and preventive automation. Mentor engineers, coach teams on operational practices, coordinate on-call coverage, and ensure infrastructure meets security and compliance requirements.
Top Skills:
AnsibleAuto ScalingAWSBashCi/CdClaudeCloudwatchCrowdstrikeDatadogDistributed SystemsDnsDockerEc2EcsGitGithub CopilotGitlabGitopsIamKubernetesLinuxLoad BalancingOracle LinuxPythonQualysRapid7RhelS3Tcp/IpTerraformVpcWireshark
Healthtech • Software
Design, automate, and maintain scalable infrastructure and SRE tooling. Manage Kubernetes clusters, CI/CD, monitoring, and incident response. Improve processes, reduce toil via automation, and collaborate with engineering and data teams to support domestic and international workloads.
Top Skills:
AWSAzureContainerdDnsDockerFirewallsGCPGoGrpcHelmKubernetesLinuxLoad BalancingPrometheusPythonRoutingShell ScriptingTcp/IpUdp

Digital Media • Gaming • Information Technology • Software • Sports • Esports • Big Data Analytics
Lead reliability, scalability, and operational excellence of large-scale database platforms across cloud and on-prem. Build automation-first database infrastructure (Kubernetes operators, IaC, GitOps), drive monitoring/SLOs, incident leadership, performance and cost optimization, and partner with application teams on safe schema/migration practices. Mentor engineers and evaluate AI-assisted workflows to improve productivity and reliability.
Top Skills:
AerospikeArgocdAuroraClaudeCloud SqlCursorDatabase OperatorsEksFluxcdGithub CopilotGitopsGkeGoKubernetesMcpMongoDBMySQLPersistent VolumesPostgresPulumiPythonRedisScylladbStatefulsetsTerraform

Healthtech • Software
Own production reliability across cloud environments by defining SLOs, SLIs, error budgets, observability practices, and actionable dashboards. Troubleshoot incidents, perform root cause analysis, manage capacity planning, and improve service performance and availability. Build automation to reduce toil, support release management, maintain runbooks, and collaborate with engineering teams on operational readiness. Manage tools including Datadog, Prometheus, and Grafana while advancing monitoring, logging, metrics, tracing, and reliability practices.
Top Skills:
.NetArgoAWSDatadogGithub ActionsGitlabGoGrafanaHelmJavaJenkinsKargoKubernetesLinuxOpentelemetryPrometheusPythonSplunkWindows
One Month AgoSaved
Easy Apply
Easy Apply
Cloud • Security • Software • Cybersecurity • Automation
Build and operate reliable, scalable production infrastructure for GitLab’s user-facing services. Responsibilities include developing infrastructure automation and tooling, managing Kubernetes deployments, maintaining infrastructure as code, supporting CI/CD and GitOps, participating in on-call and incident response, improving observability and SLOs, troubleshooting production systems, and documenting operational practices. The role spans Intermediate through Senior Staff levels and requires strong software engineering, cloud, reliability, and asynchronous collaboration skills.
Top Skills:
AlertingAWSCi/CdGCPGitopsGoInfrastructure As CodeKubernetesLoggingMetricsRubySlisSlosTerraform

Security • Cybersecurity
Develop, operate, and scale Proofpoint’s production infrastructure across global data centers and public cloud. Responsibilities include deployment, maintenance, troubleshooting, performance tuning, monitoring, alerting, capacity planning, incident response, infrastructure architecture, automation, and security. The engineer will collaborate with product and engineering teams, investigate complex system and network issues, support product rollouts, and participate in a 24x7 on-call rotation.
Top Skills:
Amazon Ec2AnsibleAWSCloudFormationDnsHTTPKvmLdapAzureNode.jsOpenstackPythonTcp/IpTerraformVmware Vsphere
New
Track Smarter, Apply Better.
Ditch the spreadsheets. Organize your job search with our freeApplication Tracker.
Use For Free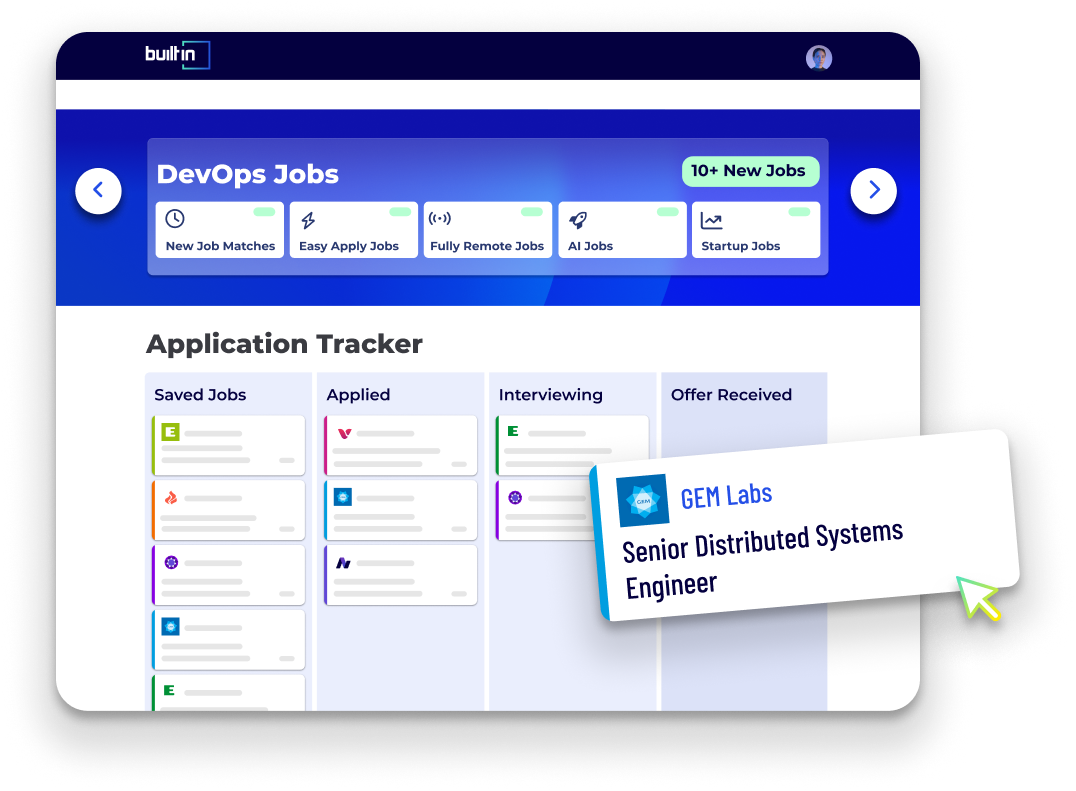

Cloud • Security
Own reliability, availability, performance, and capacity for production SaaS services across Azure, AWS, and a FedRAMP High environment. Build observability, SLOs, monitoring, infrastructure automation, and remediation workflows; lead incident response, postmortems, support escalations, and disaster recovery efforts. Manage Terraform, CI/CD, Kubernetes, WAF, networking, and observability costs while improving on-call operations and collaborating with Security, Product, Support, and Development.
Top Skills:
AksAWSAzureAzure App ServiceAzure DevopsAzure Front DoorAzure MonitorAzure Service BusAzure SqlAzure StorageAzure WafCloudflareCloudwatch Logs InsightsConsulDatadogElk StackFedrampImpervaIso 27001JenkinsJira Service ManagementJSONKubernetesMicrosoft Entra IdNist 800-53OidcPagerdutyPciPowershellPythonRedisS3SaltstackSAMLSoc 2TerraformYaml

Edtech • HR Tech • Software
Lead reliability engineering for critical SaaS services by defining SLOs, managing major incidents, improving observability, architecting scalable infrastructure, advancing deployment safety, and mentoring engineers. The role partners with engineering and product leaders to balance feature delivery with system resilience, while driving reliability standards, automation, and recruiting across the SRE organization.
Top Skills:
AWSContainer OrchestrationInfrastructure As Code

Artificial Intelligence • Software • Conversational AI • Automation
Build and improve Replicant’s AI-native platform, including site reliability, CI/CD, developer tooling, observability, incident management, cloud infrastructure, and autonomous-agent harnesses. Own production infrastructure reliability at scale, reduce operational toil, improve deployment workflows, participate in on-call rotation, and shape platform engineering patterns. The role uses TypeScript/Node.js, Python, Terraform, Kubernetes, Helm, GCP, and modern monitoring tools.
Top Skills:
ClaudeCursorDatadogFreeswitchGCPGitlab CiGrafanaHelmKubernetesLlmsNode.jsPrometheusPythonSipTerraformTypescript

Other
Build and improve Replicant’s AI-native platform infrastructure, including site reliability, CI/CD, developer tooling, observability, incident management, and agent harness systems. Own production infrastructure patterns, deployment workflows, and developer self-service across Kubernetes and cloud environments. Participate in on-call and incident response while improving scalability, availability, and operational efficiency for real-time conversational AI traffic.
Top Skills:
ClaudeCursorDatadogFreeswitchGCPGitlab CiGrafanaHelmKubernetesLlmsNode.jsPrometheusPythonSipTerraformTypescript
Artificial Intelligence • Big Data • Information Technology • Other • Software • Database • Biotech
Provides frontline support for high-availability cloud systems, monitors infrastructure, manages incidents, coordinates outage bridges, documents technical issues, and develops automation and AI agentic workflows. The role partners with development teams to improve detection and resolution, supports AWS technologies, databases, networks, CI/CD tools, and observability platforms. This is a Monday–Thursday overnight shift within a 24/7 command center and includes some holiday coverage.
Top Skills:
Ai Agentic WorkflowsAWSAws Application SignalsBashCassandraChefCi/CdCouchdbFirewallsHarnessIntrusion Detection SystemsJavaLan/WanLoad BalancersMssqlMySQLNew RelicPowershellPrompt EngineeringProxy ServersPuppetPythonTcp/IpVirtualization
eCommerce • Fintech • Payments • Software
The role involves ensuring software reliability and performance, managing incidents, developing infrastructure automation, and mentoring junior engineers within a platform team.
Top Skills:
AWSCloudFormationDatadogKubernetesOpentelemetryRubyRuby On RailsTerraform
Cloud • Security • Software • Cybersecurity
Ensure reliability, scalability, and usability of network infrastructure for Akamai Connected Cloud. Define requirements and SLOs, build automation and CI/CD pipelines, collaborate with dev/QA to improve code and stability, troubleshoot complex network issues (on-call), and mentor teammates while driving architectural standards.
Top Skills:
AnsibleArgocdBashBirdChefFrrGithub ActionsGoGobgpJenkinsLinux NetworkingPuppetPythonSalt Stack

Aerospace • Information Technology • Security • Cybersecurity • Defense
Designs and develops Python-based AWS cloud solutions, reliability tools, automation, observability, and Terraform infrastructure. Builds CI/CD pipelines, defines SRE standards and SLOs, supports incident management, and improves platform reliability through monitoring, postmortems, testing, and proactive toil reduction. Collaborates with cross-functional Agile teams to deliver scalable cloud automation across the Federal Reserve System.
Top Skills:
Automated TestingAWSAws CanaryAws CloudwatchCi/CdCloudFormationEc2EventbridgeGoGrafanaIamInfrastructure As Code (Iac)LambdaPythonS3Step FunctionsTerraformVpc

Agency • Cloud • Professional Services • Software
Improve AWS production infrastructure reliability, observability, performance, and operational maturity. Build Terraform infrastructure, enhance CI/CD, automate operational work, manage incident response and on-call operations, lead postmortems, improve application resilience, support capacity planning and database reliability, and collaborate on security hardening and compliance. Mentor engineers and promote reliability practices across the organization.
Top Skills:
AWSCi/CdCircleCIDatadogGithub ActionsGitlab CiLinuxNew RelicPostgresRubyRuby On RailsSlisSlosTerraform

Consumer Web • Gaming • Mobile • News + Entertainment • Software
Own database reliability, scalability, and operational excellence across cloud and on-premises environments. Build automated Kubernetes-based database platforms, infrastructure tooling, failover and backup systems, and self-healing capabilities. Lead observability, performance optimization, capacity planning, incident response, and safe migration practices. Partner with application teams, leverage AI for operational improvements, mentor engineers, influence architecture, and drive technical strategy for highly available database infrastructure.
Top Skills:
AerospikeArgocdAuroraClaudeCloud SqlCursorEksFluxcdGithub CopilotGitopsGkeGoKubernetesKubernetes OperatorsMcpMongoDBMySQLPersistent VolumesPostgresPulumiPythonRedisScylladbStatefulsetsTerraform
Reposted One Month AgoSaved
Easy Apply
Easy Apply
Big Data • Cloud • Software • Database
As a Senior Site Reliability Engineer, you'll design and build complex systems, support Atlas platform operations, automate processes, and ensure high availability of services.
Top Skills:
AWSAzureDnsGCPGoHTTPLinuxPythonRubyTls
Artificial Intelligence • Cybersecurity
Own and evolve the company-wide SRE strategy, reliability standards, observability practices, incident management, service ownership, SLOs, and on-call operations. Lead cross-functional reliability initiatives, establish dashboards, alerts, runbooks, and escalation paths, improve production readiness and incident response, and operate large-scale distributed systems across AWS and Kubernetes. Participate in a 24/7 on-call rotation and help shape the SRE function.
Top Skills:
Argo CdAWSDatadogGitlab CiGitopsGrafanaKubernetesNew RelicPythonTerraform

Healthtech • Software
Manage and optimize a multi-account AWS environment supporting production healthcare applications and analytics platforms. Responsibilities include AWS infrastructure administration, CI/CD and infrastructure automation, observability, incident response, on-call support, disaster recovery validation, HIPAA/HiTrust compliance, IAM and security controls, and support for containerized Java and Python applications. The role also contributes to Kubernetes and EKS modernization initiatives and partners with developers to resolve complex production issues.
Top Skills:
Amazon EksApi GatewayArgocdAuroraAWSAws CloudformationAws CodepipelineAws Security HubBashCloudfrontCloudwatchCortex CloudDatadogDockerEc2EcsFargateGitGuarddutyHelmIamJavaJenkinsKubernetesLambdaLinuxPrismaPythonRdsS3Spring BootUbuntuZabbix

Let Your Resume Do The Work
Upload your resume to be matched with jobs you're a great fit for.
Success! We'll use this to further personalize your experience.
Top Austin, TX Companies Hiring Remote Senior Site Reliability Engineers
See All





Popular Job Searches
All Filters
Total selected ()
No Results
No Results
