

Maximum of 25 job preferences reached.
Top Remote Senior Site Reliability Engineer Jobs in Austin, TX
Other • Retail
Lead and develop an SRE team responsible for the reliability, availability, performance, automation, and observability of Linux-based digital commerce infrastructure. Set SRE and DevOps strategy, modernize Kubernetes and CI/CD practices, establish automation and infrastructure-as-code standards, oversee incident response, and drive SLIs, SLOs, and error budgets. Partner across engineering, architecture, infrastructure, security, networking, and product teams while recruiting, mentoring, and developing SRE talent.
Top Skills:
Apache TomcatCi/CdDatadogDockerError BudgetsF5Github ActionsInfrastructure As CodeJfrog ArtifactoryKubernetesLinuxNginxPuppetPythonSlis/SlosTerraformVMware

Cloud • Software
The Senior Site Reliability Engineer will automate operations using Python, manage Kubernetes and OpenStack clusters, and ensure high availability for enterprise infrastructures.
Top Skills:
KubernetesLinuxOpenstackPython

Gaming
Own and operate large-scale infrastructure for sports betting and media platforms across cloud and production environments. Lead infrastructure migrations, build Kubernetes platform tooling and CI/CD automation, improve observability and alerting, support development teams, and participate in incident response. The role requires strong distributed-systems expertise, production troubleshooting, cross-team project leadership, technical communication, and mentoring.
Top Skills:
ArgocdAWSBashCephCiliumDatadogGCPGithub ActionsGoHelmIstioKubernetesLinuxPgbouncerPostgresPythonTalos OsTerraform

Cloud • Computer Vision • Information Technology • Sales • Security • Cybersecurity
Senior SRE owning availability, automation, and observability for CI/CD platform services. Build and operate infrastructure, run on-call, lead incident response, mentor engineers, drive design/capacity planning, integrate AI-assisted workflows, and improve cross-team reliability.
Top Skills:
Active DirectoryAnsibleApache AirflowSparkAWSAzureBashBazelBitbucketCassandraChefDatadogDnsFirewall RulesGCPGitGithub ActionsGitlabGitlab CiGoGrafanaHoneycombHumio/LogscaleJenkinsKafkaKubernetesLoad BalancersMongoDBMySQLNasNew RelicNfsObject StorageOpensearchOraclePostgresPowershellPrometheusPulsarPuppetPythonRabbitMQRedis/ValkeyRedpandaRoutingSaltSanSplunkTerraformVarnishVipsWindows Server

Artificial Intelligence • Cloud • Information Technology • Software
Design and operate large-scale GPU infrastructure for distributed AI training, ensuring reliability, performance, and efficient customer partnerships.
Top Skills:
AnsibleCudaDeepspeedFsdpGpuHelmInfinibandKubernetesLinuxMegatronNcclNvidia A100Nvidia B200Nvidia H100NvlinkPyTorchRoceTerraform

Reposted 2 Months AgoSaved
Easy Apply
Easy Apply
Big Data • Cloud • Software • Database
The Senior Site Reliability Engineer will develop and support distributed storage services, ensuring reliability and operational safety, with a focus on automation and efficiency.
Top Skills:
AWSAzureDnsGoGoogle Cloud PlatformKubernetesLinuxPythonTcp/IpTls

Artificial Intelligence • Information Technology • Software • Database
As a Site Reliability Engineer, you will design, implement, and maintain scalable infrastructure, ensure system reliability, automate processes, and collaborate with engineering teams.
Top Skills:
DockerElk StackGoGrafanaJavaKubernetesNode.jsPrometheusPulumiPythonRubyTerraform
Healthtech • Social Impact • Software
Own the operational lifecycle of cloud-native data infrastructure: design and automate reliable deployments, observability, incident response, SLIs/SLOs, autoscaling and IaC, and improve platform efficiency and data freshness across GKE and Cloud Run.
Top Skills:
BashBigQueryCloud BuildCloud MonitoringCloud RunDatadogDockerGCPGithub ActionsGkeGoGrafanaJIRAKubernetesPrometheusPulumiPythonSentrySlackSnykSonarqubeTerraform

Software • Consulting
Lead 24x7 application support for external web applications: manage incidents, perform RCA, implement preventative fixes, build monitoring/alerts, expand Splunk functionality, create dashboards, collaborate with development and platform teams, and participate in on-call rotation.
Top Skills:
ApmAppdynamicsAWSDatadogGrafanaKubernetesLinuxMulesoftOpenshiftOpentelemetryPostmanPythonRumSeleniumServicenowShell ScriptingSplunk (Spl)Splunk CloudSplunk Observability CloudSplunk Synthetics

Software • Financial Services
Own day-to-day AWS and database operations for a serverless production platform, manage backups and disaster recovery, monitor and debug production, lead incident response and on-call, maintain infrastructure-as-code (SST/Pulumi), optimize costs, and mentor the team on operational best practices.
Top Skills:
AWSBashCloudwatchDnsDockerEventbridgeGithub ActionsLambdaLinuxPostgresPulumiPythonS3SqsSstTerraformTlsTypescript
Insurance
Lead reliability and observability for the financial data platform: define SLOs/SLIs, build metrics pipelines, extend instrumentation across Velocity, Redpanda, MuleSoft, Snowflake, Fabric, and AWS; implement incident management (Datadog -> Incident.io -> ServiceNow), scale automation and remediation, and design AI-assisted SRE agents using Cursor for triage and root-cause analysis.
Top Skills:
Ai Coding AssistantsAWSCursorD365DatadogFabricGrafanaIncident.IoKafkaLlmsMulesoftOpentelemetryPower AppsPrometheusRedpandaServicenowSnowflakeVelocity

Information Technology • Security • Cybersecurity
Design, build, and scale Kubernetes-based, multi-tenant infrastructure and CI/CD systems. Own AI tooling infrastructure (MCP servers) and secure AI access patterns. Optimize CI/CD, streaming analytics (Kafka, Flink, ClickHouse), observability, and incident response. Implement IaC (Terraform, Helm, Pulumi), GitOps (Argo CD), progressive delivery, automated testing, and mentor engineering teams.
Top Skills:
Ai AgentsAi/Llm ToolingAksArgo CdBashClickhouseDatadogEksFlinkGithub ActionsGitlab CiGitopsGkeGoGrafanaHelmJenkinsKafkaKubernetesLangfuseLangsmithMcp ServersMlopsOpentelemetryPrometheusPulumiPythonTerraform
New
Track Smarter, Apply Better.
Ditch the spreadsheets. Organize your job search with our freeApplication Tracker.
Use For Free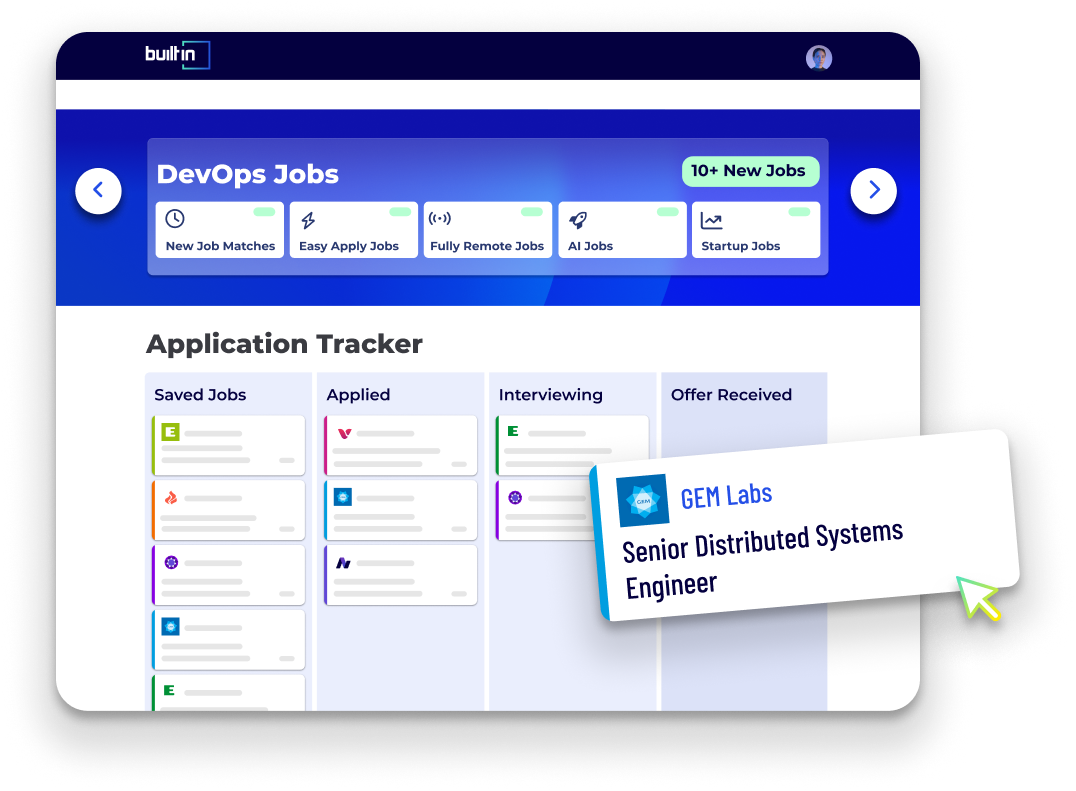

Software
Support and improve production SaaS infrastructure across AWS, colocation, and hosted platforms. Administer Windows and Linux systems, virtualization, storage, networking, and database support. Lead incident troubleshooting, root cause analysis, monitoring improvements, vulnerability remediation, automation initiatives, and medium-sized infrastructure projects. Collaborate on compliance (SOX/PCI/HIPAA), disaster recovery, and documentation to increase operational reliability.
Top Skills:
AWSBackup And RecoveryBashDatabasesFirewallsLinuxMonitoring PlatformsNetworkingPowershellPythonStorage SystemsVirtualizationWindows Server
Software • Financial Services
Lead reliability, observability, and resilience for cloud-based financial SaaS. Define SLOs/SLIs, design monitoring/tracing, own incident response and runbooks, build IaC and automation, implement AIOps, perform chaos and load testing, and write production-grade Python tooling while ensuring security and compliance.
Top Skills:
AnsibleAWSAzureBashCi/CdCloudFormationDatadogElkGitGrafanaNew RelicPowershellPrometheusPythonTerraform

Big Data
You will manage AWS infrastructure, automate deployments, debug application issues, and improve the operational health of Metabase Cloud.
Top Skills:
AWSDatadogGoGrafanaKubernetesPrometheusPythonTerraform
Real Estate • Financial Services • PropTech
Lead AWS-based SRE activities for products migrated from on-prem: ensure reliability, observability, automation, CI/CD (GitOps), Kubernetes/EKS operations, Terraform IAC, database/RDS administration, networking and security, and collaborate with development and platform teams to optimize SaaS operations.
Top Skills:
AmiArgocdAWSAws Elastic BeanstalkAws Transfer FamilyAws Well-Architected FrameworkAzure DevopsBashCloudwatchCurlDockerEc2EksFluxcdGitGitopsHTTPIstioKubernetesLinkerdLoad Balancer (Elb/Alb)PowershellPythonRdsService MeshSQLTerraformWget
Cloud • Security • Software • Cybersecurity
Lead reliability and performance efforts for distributed metadata systems: tune and optimize systems, develop monitoring and automation, manage rollouts, troubleshoot incidents, run simulations and analytics, and support database/configuration management to improve global network stability and capacity.
Top Skills:
Big DataLinuxPostgresPythonSQLUnix
Artificial Intelligence • Software
As a Software Engineer in Reliability, you'll architect and manage multi-cloud GPU infrastructure, ensuring performance, security, and scale while debugging complex hardware/software issues.
Top Skills:
AmdAWSBashGoGpuInfinibandLinuxNvidiaOciPythonRdma
Reposted One Month AgoSaved
Software • Cybersecurity
This role involves managing Kubernetes clusters, cloud infrastructure, and CI/CD pipelines. The engineer will enhance system reliability and efficiency while troubleshooting production issues.
Top Skills:
AlertmanagerAWSAzureBashCi/CdDockerElastic StackElasticsearchGCPGoGrafanaHelmKafkaKubernetesLokiMongoDBOciPrometheusPythonRedisSparkTerraform
Software
The role involves managing compute infrastructure for decentralized applications, requiring critical thinking, documentation skills, and experience in Kubernetes and blockchain management.
Top Skills:
BlockchainGitopsInfrastructure-As-CodeKubernetesProgramming Languages

Artificial Intelligence • Other • Sales • Software
The role involves designing and advancing infrastructure for the engineering team, ensuring the reliability of Kubernetes clusters, automating operations, and building machine learning infrastructure.
Top Skills:
ArgoAWSAzureCloudFormationFluxGithub ActionsGoGCPKubernetesPostgresPythonTerraform
Cloud • Software
As a Site Reliability / Gitops Engineer, you will automate operations, develop Infrastructure as Code, maintain core services, and collaborate on service architecture.
Top Skills:
Ci/CdCloud ComputingElasticsearchGrafanaInfrastructure As CodeLinuxPrometheusPython
Cloud • Software
The Senior Site Reliability / Gitops Engineer will drive automation and collaboration within the IS team, enhancing Canonical's IT operations and services while managing infrastructure as code and cloud technologies.
Top Skills:
Cloud ComputingDockerElasticsearchGitopsGrafanaIacKubernetesLinuxPrometheusPython
Information Technology • Marketing Tech • Social Media
Lead technical design and architecture of large-scale Ceph clusters, drive capacity planning and major upgrades, resolve complex cross-functional production incidents, establish automation and reliability standards, and mentor engineers on advanced Ceph operations to scale the global storage platform.
Top Skills:
AnsibleBluestoreCephCephfsCinderCrushCsiDdnErasure CodingGoIsilonKubernetesManilaMdsMgrMonNetappNeutronNovaOpenstackOsdPlacement GroupsPurePythonRbdRbd MirroringRgwRgw MultisiteRookS3SaltstackSwiftTerraformVastWeka

Let Your Resume Do The Work
Upload your resume to be matched with jobs you're a great fit for.
Success! We'll use this to further personalize your experience.
Top Austin, TX Companies Hiring Remote Senior Site Reliability Engineers
See All






Popular Job Searches
All Filters
Total selected ()
No Results
No Results
