

Maximum of 25 job preferences reached.
Top SRE Engineer Jobs in Austin, TX
Cloud • Software
Lead the architecture, operation, and reliability of Cisco ThousandEyes’ FedRAMP-compliant AWS GovCloud platform. Build resilient cloud-native services using infrastructure as code, maintain high availability and security for high-volume data streams, automate compliance controls and auditing, and optimize multi-region infrastructure. Collaborate with engineering and security teams, lead technical initiatives, address operational risks, and establish engineering standards for regulated environments.
Top Skills:
AWSKubernetesPythonTerraform

Healthtech • Payments • Software
Leads reliability engineering for critical platforms by improving scalability, performance, observability, automation, and incident response. Designs SLOs, error budgets, monitoring, recovery mechanisms, and infrastructure solutions; conducts root cause analyses and postmortems; supports distributed systems, Kubernetes, cloud platforms, IaC, and CI/CD pipelines. Provides technical leadership across engineering teams, mentors engineers, and applies AI tools to automate workflows and improve operational efficiency.
Top Skills:
AWSAzureBashCi/CdCloudFormationGCPGoGrafanaKubernetesPowershellPrometheusPythonSplunkTerraform
Gaming • Information Technology • Mobile • Software • Esports
Lead the design, operation, and reliability of hybrid AWS and VMware infrastructure supporting game services and millions of players. Manage cloud platforms, databases, networking, load balancers, observability, automation, security, CI/CD, incident response, and disaster recovery. Establish SRE practices, SLIs, SLOs, error budgets, runbooks, and post-mortem improvements while partnering with engineering and game studios.
Top Skills:
1PasswordAfmAlbAnsibleAs3AuroraAWSAws ConfigAws Fault Injection ServiceAws Secrets ManagerAws Systems ManagerCloudfrontCloudwatchDatadogDirect ConnectDnsDns/GtmEc2ElbEsxiF5 Big-IpGithub ActionsGoGrafanaIamIcontrol RestIrulesJenkinsLinuxLtmMySQLNlbNsxOpen Policy AgentOpentelemetryPackerPasswordstatePgbouncerPostgresPrometheusProxysqlPuppetPythonRdsRoute 53S3Service Control PoliciesTcp/IpTerraformTlsTransit GatewayTypescriptVcenterVmware VsphereVpcVsan
AdTech
Build and maintain cloud-native infrastructure, automate manual operations, develop Terraform modules and Helm charts, manage Kubernetes and service mesh configurations, monitor GCP databases and services, improve observability, maintain CI/CD pipelines, and use AI coding agents to enhance infrastructure development. Collaborate with engineering teams on instrumentation, architecture, capacity planning, scalability, reliability, security, and developer experience.
Top Skills:
Amazon KinesisAWSAws LambdaAws SnsBigQueryClaude CodeCloudsqlCursorDatadogDockerGCPGitlabGoogle Cloud FunctionsGoogle Cloud RunGoogle Pub/SubGrafanaHelmIstioKafkaKubernetesMySQLPrometheusSpannerTerraform

Reposted 15 Days AgoSaved
Cloud • Computer Vision • Information Technology • Sales • Security • Cybersecurity
Lead architecture and implementation of reliability improvements across CrowdStrike's cloud-native platform. Build shared libraries and services, drive observability and SLO practices, perform performance and cost optimization, run resilience engineering and chaos experiments, automate infrastructure-as-code, mentor engineers, and embed with product teams to deliver scalable, highly reliable distributed systems at organizational scale.
Top Skills:
AIAlertingAWSCassandraElasticsearchGCPGoInfrastructure-As-CodeJavaKafkaKotlinKubernetesNode.jsObservability (TracingOciOpensearchProfilingProtobufPythonScalaSlos)
Big Data • Real Estate • Software
Senior Site Reliability Engineer responsible for improving reliability, observability, resilience, and cost efficiency across AWS and Kubernetes infrastructure. The role manages EKS, CI/CD, API gateway, GraphQL, and monitoring platforms; implements reliability patterns, dashboards, alerts, FinOps practices, chaos engineering, disaster recovery, and incident response. It requires strong infrastructure automation, programming, Infrastructure as Code, GitOps, and distributed-systems expertise, along with participation in on-call rotations and cross-functional technical collaboration.
Top Skills:
Apollo GraphqlArgo CdAWSAws Secrets ManagerBashCircleCICloudFormationCloudfrontCloudwatchDatadogDockerEc2Ecs FargateEksGithub ActionsGoGrafanaHelmIamIstioJavaJenkinsKubernetesKustomizeLambdaNew RelicOpsgeniePagerdutyPrometheusPythonRdsRoute 53S3ServicenowSplunkTerraformTyk GatewayVaultVpc
Aerospace • Hardware • Information Technology • Security • Software • Cybersecurity • Defense
Deploys, monitors, automates, and supports large-scale distributed infrastructure and applications across IaaS, PaaS, and SaaS environments. Responsibilities include implementing SRE practices, scaling systems through automation, monitoring production performance, resolving complex service issues, and providing operational engineering support. The role collaborates with Core Services, DevOps, Security, and IT Operations teams and requires networking, cloud, storage, virtualization, infrastructure-as-code, and site reliability expertise.
Top Skills:
Amazon S3AnsibleAzure StackCephHelmIaasInfrastructure As CodeJdfsJuniperKubernetesNfsObject StorageOpenstackPaasSaaSSecurity+TerraformVMware

Cloud • Information Technology • Internet of Things • Professional Services • Software
Lead the architecture, operation, and reliability of Cisco ThousandEyes’ FedRAMP-compliant US GovCloud platform. Design resilient AWS services using infrastructure as code, maintain high availability and security for large-scale data streams, automate compliance controls and auditing, and collaborate with engineering and security teams on multi-region infrastructure, risk management, incident response, and technical strategy.
Top Skills:
AWSFedrampHipaaKubernetesPci-DssPythonSoc 2Terraform
Cloud • Information Technology • Internet of Things • Professional Services • Software
Leads the migration of globally distributed Kubernetes workloads from AWS to an internal platform, establishes technical direction, and supports production reliability. Responsibilities include incident response, performance optimization, observability, automation, networking, security, operational readiness, and production-quality Go development for distributed systems. The role partners across infrastructure, security, SRE, product, and application teams while contributing to Kubernetes platform reliability and scalability initiatives.
Top Skills:
Amazon EksAWSDatadogDnsDockerGitlab Ci/CdGoGrpcIpv4Ipv6KubernetesKustomizeLinuxMutual TlsOpentelemetryPkiPrometheusProtocol BuffersTcpTlsVpn

Fintech • Information Technology • Insurance • Financial Services • Big Data Analytics
Leads architecture, modernization, optimization, and reliability initiatives for mainframe CICS, MQ, and z/OS Connect environments. Provides technical direction across development and operations teams, establishes governance and change processes, tunes performance using telemetry, resolves incidents, and develops modernization roadmaps. Collaborates with stakeholders and enterprise architects to deliver secure, scalable, high-availability solutions while evaluating automation, cloud integration, and AI technologies.
Top Skills:
AnsibleCicsCobolDevOpsIbm MqIbm Z/OsOpenshiftPythonRed Hat Ansible Automation PlatformZ/Os ConnectZlinux
27 Days AgoSaved
Easy Apply
Easy Apply
Cloud • Security • Software • Cybersecurity • Automation
Provide technical direction for GitLab Dedicated, a managed single-tenant SaaS platform. Lead architecture and transformation across resilience, failover, tenant orchestration, change management, automation, and platform integrations. Identify systemic reliability and scalability risks, establish reusable platform patterns, strengthen service ownership, and guide cross-team technical decisions. Mentor senior engineers and advance engineering excellence across the organization.
Top Skills:
Cloud InfrastructureDevsecopsDistributed SystemsGoInfrastructure As CodeObservabilityPythonRuby

Artificial Intelligence • Computer Vision • Hardware • Robotics • Metaverse
Design, build, and operate global, multi-cloud HPC service platforms. Own IaC-driven provisioning, reliability, observability, capacity planning, incident response, and automation to ensure high uptime and QoS for internal customers.
Top Skills:
AiopsAWSCi/CdContainer ManagementGCPGoInfrastructure As CodeKubernetesLog CollectionLsfMetricsMonitoringObservabilityOciPerlPythonRubySlurm
New
Cut your apply time in half.
Use ourAI Assistantto automatically fill your job applications.
Use For Free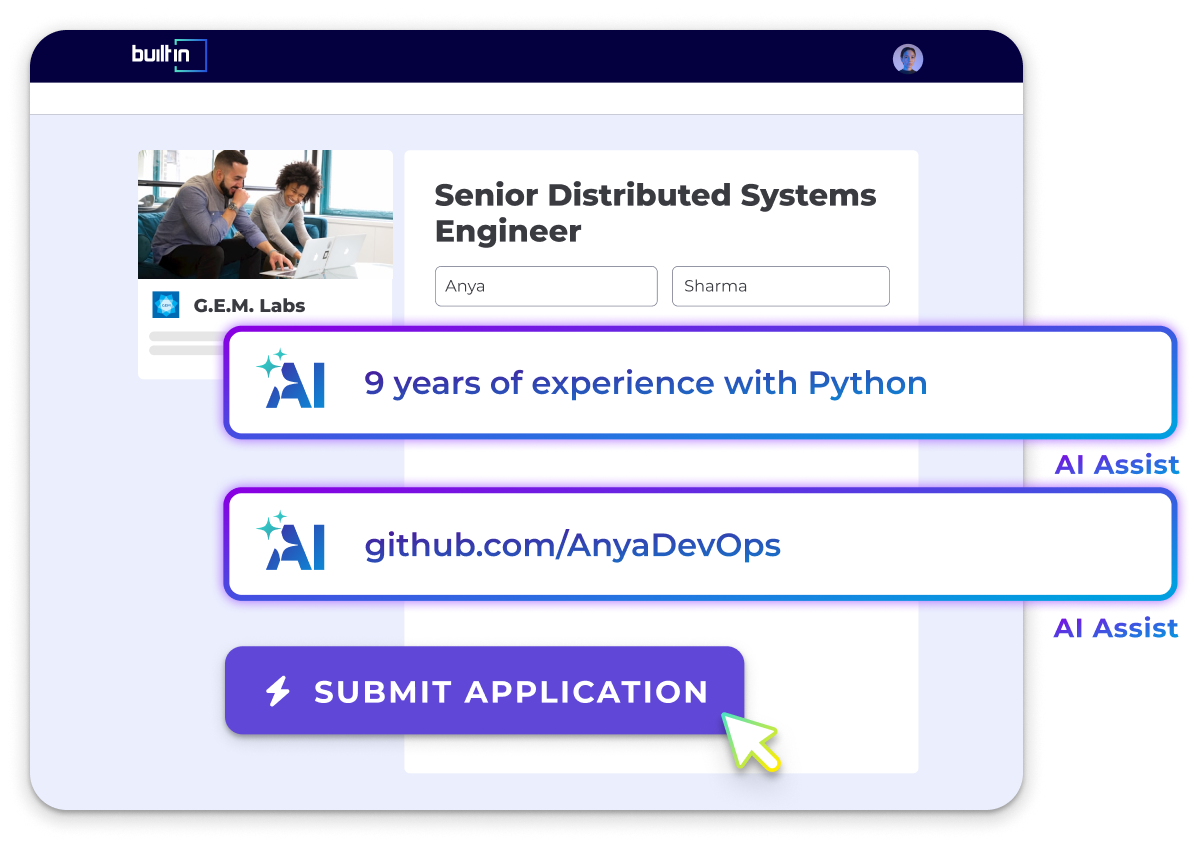
Healthtech
Lead the evolution of Azure infrastructure toward Kubernetes-based, microservices-oriented systems. Design reliable and scalable cloud infrastructure, observability, networking, CI/CD pipelines, and Infrastructure-as-Code. Drive incident response, cost optimization, capacity planning, performance improvements, and automation while partnering with engineering and data teams. Document best practices, mentor colleagues, and support platform strategy in a healthcare environment with PHI, access control, and audit requirements.
Top Skills:
.NetAWSAzureAzure Entra IdBashC#DatadogGCPGithub ActionsGitlab Ci/CdGrafanaHelmKubernetesPrometheusPythonTerraform

Healthtech • Software
Provide technical leadership for site reliability engineering, applying software engineering practices to large-scale operations. Design automated, repeatable operational solutions; monitor service objectives, application performance, and business metrics; improve resiliency, efficiency, and cost. Support cloud and on-premise infrastructure, production applications, deployment automation, testing, and vulnerability response. Partner with software development, security, and business teams while promoting Agile practices, change management, training, and operational health.
Top Skills:
AnsibleAzureCC++ChefDockerEcsGithub CopilotGoJavaKubernetesLinuxPerlPuppetPythonRubyTerraformWindows
Artificial Intelligence • Cloud • Information Technology • Consulting
Internship SRE role responsible for availability, performance, and scalability of an e-commerce supply-chain platform. Tasks include SLO/SLA definition, observability (Prometheus/Grafana/Loki/Tempo/OpenTelemetry), incident response, capacity planning, disaster recovery for PostgreSQL, infrastructure-as-code (Terraform), CI/CD automation, and operational reliability for AI agent services. Mentored by Head of Technology/CTO with potential conversion to full-time based on performance.
Top Skills:
BashCi/CdDockerGrafanaLangchainLlmLokiMakefileNestjsOpentelemetryOracle CloudPgbackrestPostgresql 15PrometheusPythonRedisTempoTerraformTraefik

Cloud • Information Technology
Principal Site Reliability Engineer responsible for the availability, scalability, durability, and operational reliability of production systems. The role leads observability, incident response, SLO and error-budget practices, automation, infrastructure as code, and long-term service improvements. Responsibilities include designing monitoring and alerting frameworks, supporting Kubernetes and distributed storage environments, improving operational processes, collaborating across engineering and business teams, and mentoring reliability-focused practices. The position requires extensive experience with Linux, cloud infrastructure, containers, scripting, storage systems, and large-scale production environments.
Top Skills:
AnsibleAWSAzureBashCatchpointDockerElkError BudgetsFirehydrantGCPGoGrafanaHashicorp NomadHashicorp VaultIpvsItilJenkinsKubectlKubernetesLinuxMysqlshPrometheusPythonSlisSlosTerraformVitess

Computer Vision • Software
Build and maintain CI/CD pipelines, deployment automation, and cloud infrastructure across Azure and AWS. Manage observability with Datadog or Dynatrace, improve incident response and MTTR, provision infrastructure with Terraform, and develop automation scripts using Python, Bash, or PowerShell. Collaborate across VA engineering programs, improve platform stability, mentor junior engineers, and establish DevOps standards in a remote Agile environment.
Top Skills:
AgileAWSAzureBashCi/CdDatadogDynatraceGithub EnterprisePowershellPythonTerraformVa PlatformVa.Gov

Healthtech • Pharmaceutical
Own the reliability, availability, performance, observability, and security of Ophelia’s GCP telehealth platform. Define SLOs, improve monitoring and incident response, expand Terraform infrastructure, strengthen CI/CD, manage disaster recovery, and address latency and Cloud Run performance. Lead on-call maturity, HIPAA/SOC 2 infrastructure controls, and reliability education for engineers. Use AI-assisted tools for automation and incident triage while partnering with technical and non-technical stakeholders.
Top Skills:
BigQueryClaudeCloud RunFirebaseFirebase AuthenticationFirebase HostingFirestoreGeminiGithub ActionsGoogle Cloud OperationsGoogle Cloud PlatformIamNode.jsPagerdutyPythonReactShell ScriptingSQLTerraformTypescript

Artificial Intelligence • Blockchain • Software • Cryptocurrency
Operate and improve large-scale AI compute, storage, and networking infrastructure in 24x7 environments. Responsibilities include capacity planning, performance analysis, patching, upgrades, firmware management, automation, incident response, documentation, disaster recovery testing, and L3 escalation support. The role also requires customer collaboration, operations enablement, and participation in an on-call rotation while supporting OpenStack or similar private cloud platforms.
Top Skills:
Automation ScriptingBgpDatabase TechnologiesInfrastructure As CodeLoad BalancingNsxOpenstackOspfRoutingSoftware-Defined NetworkingSwitchingVlanVxlan

Security
Own infrastructure reliability across GCP, Kubernetes, PostgreSQL, and hundreds of cloud projects. Build automation and software that eliminate toil, reduce manual on-call work, address latency and reliability trade-offs, and provide system health visibility. Lead infrastructure projects, define service-level objectives with product teams, improve reliability practices, and develop production systems for agent-first applications.
Top Skills:
GCPKubernetesPostgres

Artificial Intelligence • Healthtech • Software • Telehealth
Design, deploy, and maintain resilient AWS and Kubernetes infrastructure. Build automation, internal tools, CI/CD components, and AI-assisted operational workflows. Establish observability, SLIs, SLOs, and incident-management practices while leading postmortems and reducing toil. Ensure HIPAA compliance, review architecture, identify risks, and mentor engineers on reliability and platform best practices.
Top Skills:
Amazon Ec2Amazon EksAmazon RdsAmazon S3AWSBashDatadogGithub ActionsGoHelmHipaaKubernetesPythonTerraform
Database
Embed with service teams to define SLIs/SLOs and error budgets, run Operational Readiness Reviews, improve incident-to-improvement pipelines, advise on resilience and architecture, reduce operational toil through automation, and shape org-wide on-call practices and operational maturity.
Top Skills:
AWSCdkGrafanaKubernetesOpentelemetryPostgresPulumiTerraformVictoriametrics

Sports
Manage and improve CI/CD pipelines, containerized deployments, AWS infrastructure, Terraform resources, monitoring, and incident response for the SportsRecruits platform. Troubleshoot application, database, and distributed-system performance issues; maintain development and QA environments; collaborate with engineering, QA, product, and security teams; and implement automation, observability, scalability, and AI-assisted monitoring improvements.
Top Skills:
Amazon CloudwatchAmazon Ec2Amazon EcsAmazon RdsAws EcrAws LambdaBashBitbucket PipelinesDockerGithub ActionsNew RelicPHPPythonSentryTerraform
Software
Own and scale Drivetrain’s multi-cloud AWS and GCP infrastructure, Kubernetes platforms, CI/CD pipelines, Terraform modules, automation, observability, and security practices. Drive reliability engineering through capacity planning, incident response, postmortems, and SLI/SLO/SLA management. Partner with development teams to improve application deployability, scalability, resilience, and operational efficiency across the SaaS platform.
Top Skills:
AWSAws CloudwatchDockerEfkElkGCPGcp Operations SuiteGitGrafanaIstioJenkinsKubernetesKustomizeLinkerdPrometheusPythonTerraform
Legal Tech • Software
Lead observability and incident management efforts: define SLIs/SLOs, build monitoring/alerting, dashboards, logging, and tracing. Drive incident response, postmortems, and reliability improvements to reduce MTTD/MTTR. Integrate observability into CI/CD, maintain AWS and Kubernetes infrastructure, automate operations, and mentor engineers on SRE best practices.
Top Skills:
AWSBashCi/CdDatadogDistributed TracingDynatraceGrafanaKubernetesNew RelicOpentelemetryPowershellPrometheusPython

Let Your Resume Do The Work
Upload your resume to be matched with jobs you're a great fit for.
Success! We'll use this to further personalize your experience.
Top Austin, TX Companies Hiring SRE Engineers
See All






Popular Austin, TX Engineering Job Searches
Engineering Jobs in Austin, TX
.NET Developer Jobs in Austin, TX
Android Developer Jobs in Austin, TX
Application Engineer Jobs in Austin, TX
Automation Engineer Jobs in Austin, TX
Backend Engineer Jobs in Austin, TX
C# Jobs in Austin, TX
C++ Jobs in Austin, TX
Cloud Engineer Jobs in Austin, TX
Controls Engineer Jobs in Austin, TX
CTO Jobs in Austin, TX
Design Engineer Jobs in Austin, TX
DevOps Engineer Jobs in Austin, TX
DevOps Jobs in Austin, TX
Director of Engineering Jobs in Austin, TX
Electrical Engineering Jobs in Austin, TX
Embedded Software Engineer Jobs in Austin, TX
Engineering Manager Jobs in Austin, TX
Field Engineer Jobs in Austin, TX
Front End Developer Jobs in Austin, TX
Full Stack Developer Jobs in Austin, TX
Golang Jobs in Austin, TX
Hardware Engineer Jobs in Austin, TX
Infrastructure Engineer Jobs in Austin, TX
iOS Developer Jobs in Austin, TX
Java Developer Jobs in Austin, TX
Javascript Jobs in Austin, TX
Linux Jobs in Austin, TX
Manufacturing Engineer Jobs in Austin, TX
Mechanical Design Engineer Jobs in Austin, TX
Mechanical Engineering Jobs in Austin, TX
Network Engineer Jobs in Austin, TX
PHP Developer Jobs in Austin, TX
Platform Engineer Jobs in Austin, TX
Principal Software Engineer Jobs in Austin, TX
Process Engineer Jobs in Austin, TX
Product Engineer Jobs in Austin, TX
Project Engineer Jobs in Austin, TX
Python Jobs in Austin, TX
QA Engineer Jobs in Austin, TX
QA Jobs in Austin, TX
Robotics Engineer Jobs in Austin, TX
Ruby Jobs in Austin, TX
Salesforce Developer Jobs in Austin, TX
Scala Jobs in Austin, TX
Security Engineer Jobs in Austin, TX
Software Engineer Jobs in Austin, TX
Software Engineering Manager Jobs in Austin, TX
Software Test Engineer Jobs in Austin, TX
Solutions Architect Jobs in Austin, TX
Solutions Engineer Jobs in Austin, TX
SRE Engineer Jobs in Austin, TX
Staff Software Engineer Jobs in Austin, TX
Systems Engineer Jobs in Austin, TX
Web Developer Jobs in Austin, TX
All Filters
Total selected ()
No Results
No Results
